Yunnan2026-10-20 01:26:11Yunnan’s shift from tobacco and power to Token-priced compute puts AI on a resource trade pathYunnan’s industrial story is being retold through a familiar mechanism: turn local resources into tradable products. The article traces that arc from tobacco to hydropower, then to green aluminum and now compute sold in Token units, starting with a retail example in Kunming where 9.9 yuan a month buys 10 million Tokens. It argues that the same logic that turned low-cost hydropower into aluminum output is now being applied to data centers, servers, and cross-border communications infrastructure. The report also moves from provincial industry policy to what happens inside companies. Using Yunnan Hengtong Coal Industry and Yunnan Normal University as examples, it shows how AI deployment is less about buying software than about breaking work into clear tasks, defining rules, handling exceptions, and feeding business knowledge into systems. In Hengtong Coal’s case, WPS Comate cut a process that once took more than two hours down to minutes, but only after staff reworked workflows and split a task that had hit a 1 million-Token context limit. The broader point is that projects and infrastructure can be imported quickly, while the ability to absorb technology and turn it into routine productivity has to be built inside the organization over time.190
Anthropic2026-10-17 03:01:37Anthropic launches Claude Code Review for Team and Enterprise users, cutting review times to 6-10 minutesAnthropic has moved Code Review, the automated review feature inside Claude Code, out of research preview and into general availability for Team and Enterprise customers. The tool, first introduced in March this year, runs multiple agents in parallel after a developer submits a GitHub pull request, checking for logic flaws, security issues, and edge-case problems. It then cross-validates findings to reduce false positives and posts the detected issues, trigger conditions, and suggested fixes directly on the relevant lines of code. According to Anthropic, most reviews now finish in 6 to 10 minutes, compared with about 20 minutes during the preview period, bringing the process close to three times faster. Admins can also choose among Quick, Standard, and Deep review modes for different repositories. Claude Code founder Boris Cherny said he uses Code Review on all of his pull requests and that the tool catches nearly all bugs before merge. The feature is not included in standard Claude subscription usage and carries a separate charge. Anthropic previously said reviews cost $15 to $25 on average, with final pricing based on token consumption. More complex code and deeper review settings usually cost more.290
Anthropic2026-10-08 00:00:37Anthropic launches Claude Haiku 5.5 with average runtime costs down about 75%Anthropic has introduced Claude Haiku 5.5, describing it as its lowest-cost, fastest, and most capable small model so far. The company said the model is built for high-volume use cases including summarization, context compression, database queries, classification, sub-agents, real-time customer support, and browser operations. Haiku 5.5 is also the first model in the Haiku line to support adjustable reasoning strength. On pricing, Anthropic said the model’s average runtime cost is about 75% lower than Haiku 4.5. For workloads within 100,000 tokens, input and output are priced at $0.10 and $0.50 per million tokens, respectively. The company also cut Sonnet 5.5 cache read pricing by 50%, a change it expects will reduce costs for most Sonnet 5.5 agent tasks by about 20%. In addition, Anthropic said Max 5x, Max 20x, and Team users will receive monthly API credits of $100, $200, and up to $500, respectively.340
SpaceXAI2026-09-21 15:49:43SpaceXAI launches Grok 4.7 with lower pricing and faster speedSpaceXAI has launched Grok 4.7, according to ChainCatcher. The new product is described as running at twice the speed of comparable offerings while costing half as much. Pricing details released in the brief update show input tokens at $2 per 1 million tokens and output tokens at $6 per 1 million tokens. No other product specifications or launch details were disclosed in the source. The announcement was categorized under market analysis by ChainCatcher.410
Ramp2026-09-10 00:36:04Ramp AI Index shows Anthropic at 43.8% of paying U.S. businesses in AugustRamp chief economist Ara Kharazian released the September 2026 Ramp AI Index on Sept. 9, using Ramp spending data to track AI usage among U.S. businesses. In August, Anthropic held a 43.8% share among U.S. companies paying for AI subscriptions or tokens, up 0.34 percentage points from the prior month, while OpenAI stood at 39.8%, up 0.09 points. The report said new AI adoption continued to grow, though the pace slowed, with information, finance, and professional services leading. It also showed that median monthly AI spending per employee among the top 1% of firms fell 9.7%, from $7,976 to $7,205. Effective pricing per 1 million tokens dropped 41% from a March 2026 peak of $1.15 to $0.68. Cheaper standard models drove usage, while frontier models Opus, Fable, and Sol accounted for 45% of token share. Open-source model adoption remained limited at 6.4% of AI-spending firms and 3.6% of all firms.1290
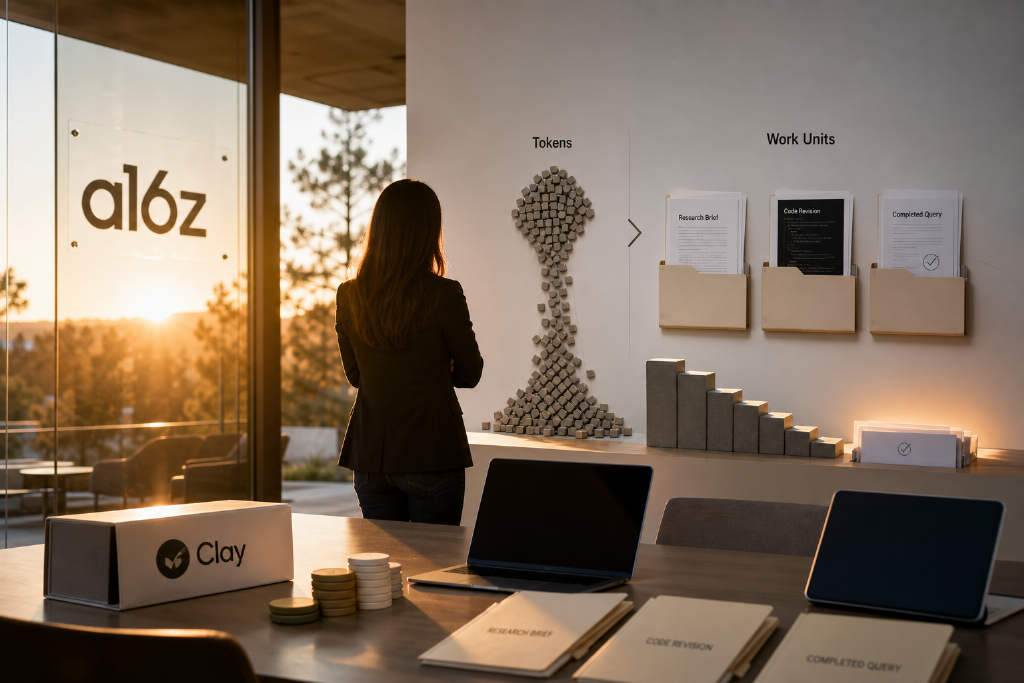
a16z2026-08-28 00:40:49a16z Partner Sarah Wang Says AI Applications Should Not Be Priced by Tokena16z partner Sarah Wang said in a recent post that AI application-layer products should not copy model-layer token pricing. Instead, she argued, they should be priced around customer-recognizable units of work. Her core point is that token pricing ties application value to a unit whose cost keeps falling, while also making it hard for customers to predict context length, retrieval volume, or inference time. It can also push buyers to compare an application with raw compute in ways that do not reflect the product’s actual value. Wang proposed a tiered pricing framework based on value. Under that structure, model layers can still charge by token, while application layers should charge by identifiable work units such as an account research brief, a code edit, or a completed query, potentially packaged through credits. In scenarios where attribution is clear and value is easy to define, she said products can charge directly by outcome, such as a resolved customer service conversation or a qualified lead. She cited Clay as an example, noting that its new pricing separates Data Credits from Actions and passes through inference-model cost fluctuations without markup.1070
DeepSeek2026-08-16 13:14:01DeepSeek V4 Flash tops rankings, but posts only a 53.8% pass rate in independent testDeepSeek V4 Flash reached the top of a ranking, but its showing in an independent evaluation was far weaker. According to Techub, citing CryptoBriefing, Composio tested the model on complex agent tasks and found it completed only 53.8% of them. The evaluation covered 30 multi-step workflows and included 240 runs across real-world tools such as Gmail, GitHub, and Slack. Results also showed wide performance gaps across agent frameworks. Pi Agent delivered the best outcome, completing 20 tasks. The report added that DeepSeek V4 Flash has an input token price as low as $0.14 per million, roughly one-tenth of comparable products, but said the high failure rate could create extra computing and debugging costs. The findings point to a gap between leaderboard standing and execution in tool-based, multi-step workflows.800
AI2026-07-24 04:20:15Companies Tighten Internal AI Limits After Uber Burned Through Its Annual Budget by AprilLarge companies are capping internal AI use after token-based pricing drove costs sharply higher. With spending harder to predict, executives are asking whether enterprise AI usage is producing measurable business value.500